Puro-2B: Poor Lab's Qwen2-1.5B Trained on RTX 5090 within $5090
Training a 2B language model on consumer GPUs becomes practical when data, optimization, and FP8 systems are designed together.
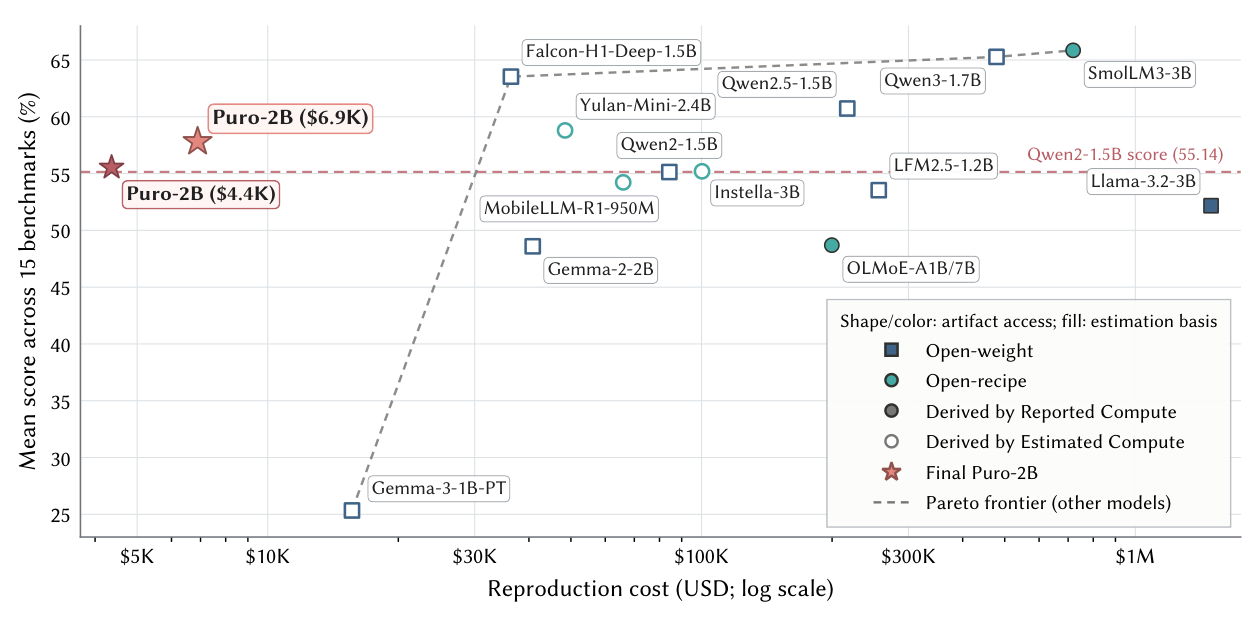
This report presents an open, cost-efficient recipe for pretraining 2B language models on consumer-grade RTX 5090 GPUs. It releases the training data, code, and model weights, and studies how hardware, low-precision training, optimization, curriculum model averaging, and data choices affect cost and performance.
I led the project and am a co-first author, listed first. The recipe demonstrates trillion-token FP8 pretraining on consumer GPUs.
Kairong Luo, Jiarui Cui, Yaorui Yin, Shengqi Chen, Yiming Yang, Linxiang Gao, Yanmohan Wang, Chengxia Li, Mingzhe Zhang, Kaifeng Lyu, and Wenguang Chen. (2026). "Puro-2B: Poor Lab's Qwen2-1.5B Trained on RTX 5090 within $5090." Technical Report.