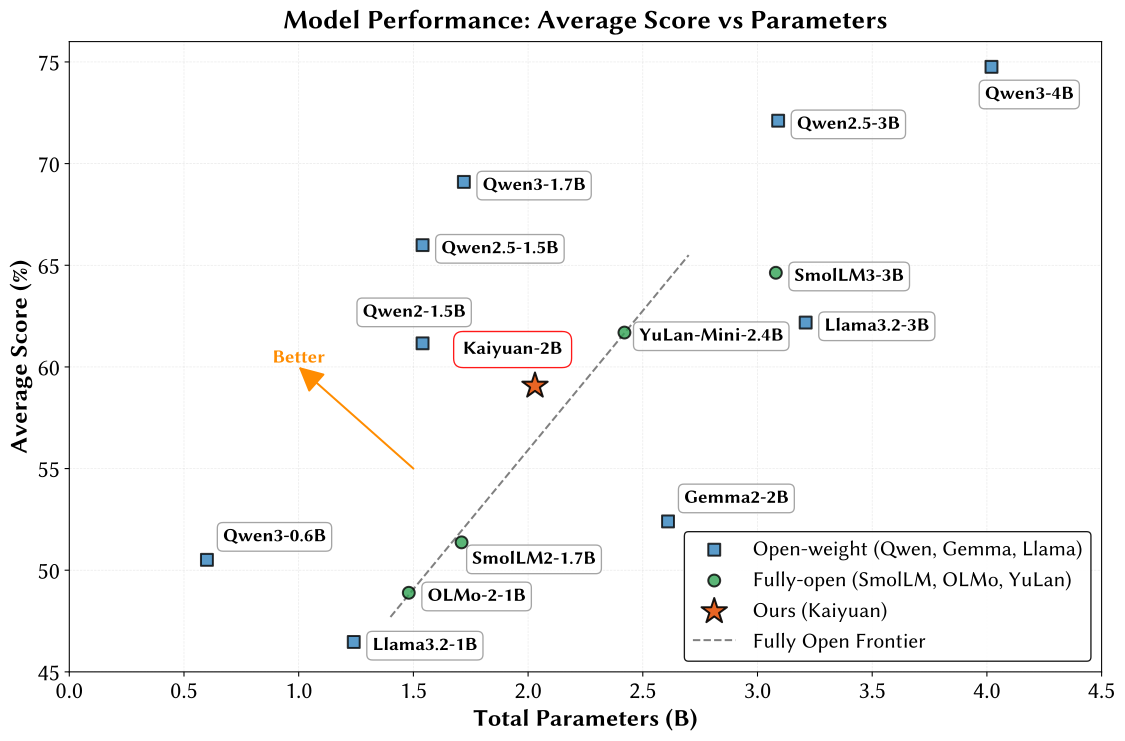
Open LLM Pretraining Guided by Quantile Benchmarking Heterogeneous Web Corpora
Comparing web corpora across quality quantiles helps choose better data mixtures for open LLM pretraining.
On data, optimization, and making pretraining more accessible. Google Scholar
Comparing web corpora across quality quantiles helps choose better data mixtures for open LLM pretraining.
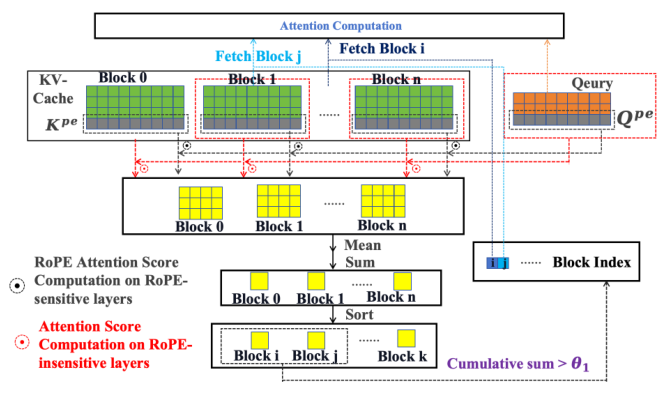
Training-free blockwise sparse attention for MLA reduces long-context decoding latency with minimal accuracy loss.
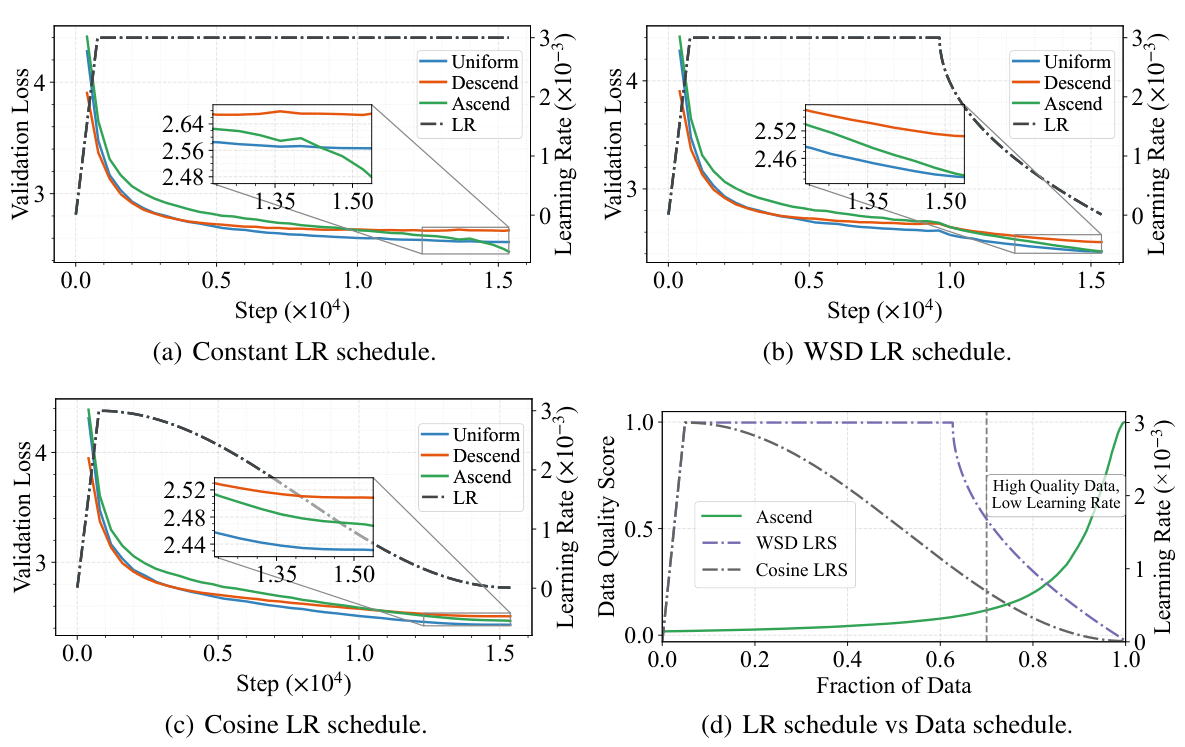
Learning-rate decay weakens late-arriving high-quality data, while moderate decay and curriculum model averaging recover its training benefits.
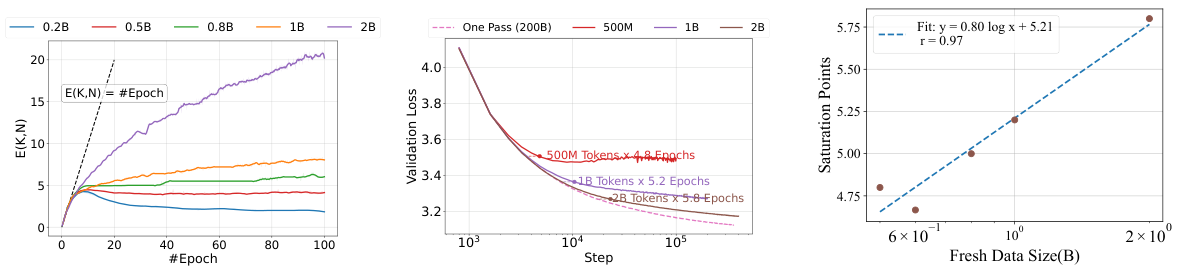
Theory and LLM experiments show why larger datasets can be repeated more: useful reuse depends on both dataset size and distribution.
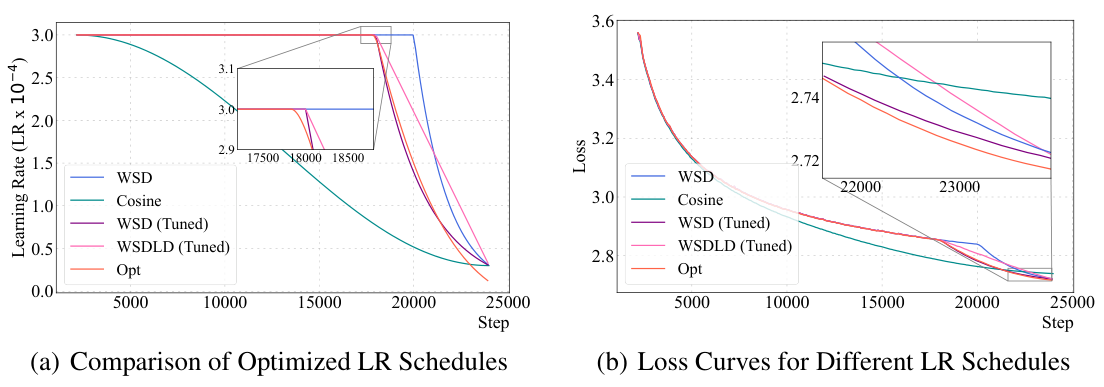
A multi-power law predicts loss under unseen learning-rate schedules, turning schedule selection from trial and error into a guided search.
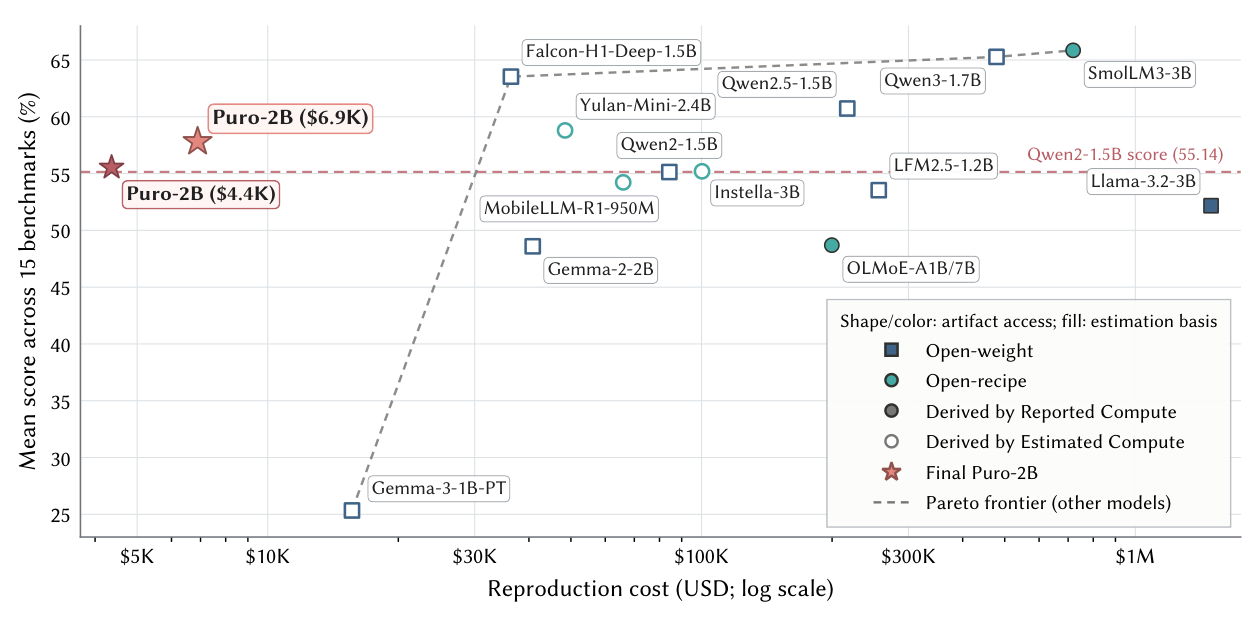
Training a 2B language model on consumer GPUs becomes practical when data, optimization, and FP8 systems are designed together.
An end-to-end open 2B pretraining stack releases the data, processing tools, training code, and model weights needed for reproducible research.
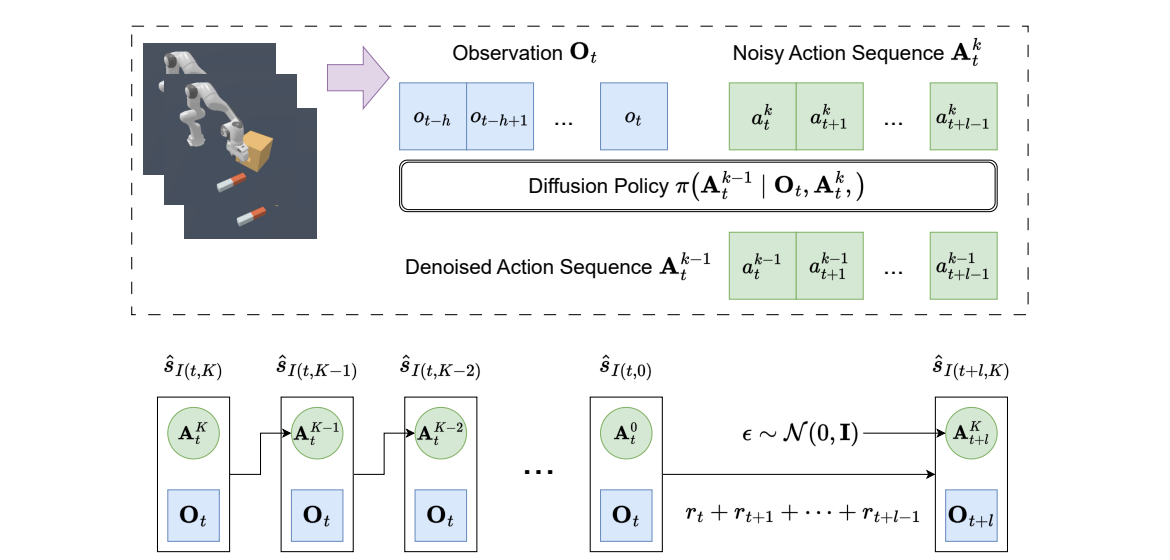
A trajectory-based value optimization approach that combines diffusion policy learning with efficient Q-function learning for offline reinforcement learning.