Puro-2B: How Can a Poor Lab Pretrain a Model from Scratch?
Puro-2B:普通实验室也能做预训练?
A practical account of pretraining on RTX 5090 GPUs, with the data recipe, optimizer choices, and interactive experiments.
Read articlePh.D. student · Computer Science · Tsinghua University
I am advised by Wenguang Chen in the PACMAN Lab, and work closely with Kaifeng Lyu and Shengding Hu.
I study how data and optimization shape language model pretraining, and turn these insights into efficient, fully open training recipes.
Previously, I received my B.Eng. from Tsinghua’s Yao Class in 2024.
Puro-2B:普通实验室也能做预训练?
A practical account of pretraining on RTX 5090 GPUs, with the data recipe, optimizer choices, and interactive experiments.
Read article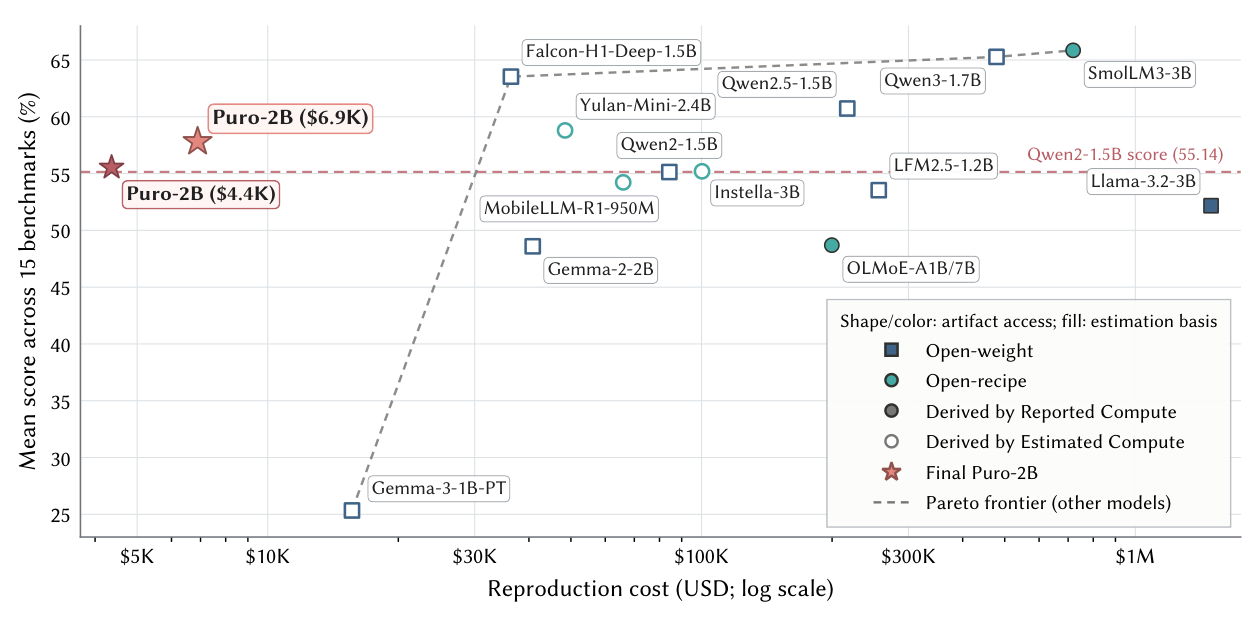
Training a 2B language model on consumer GPUs becomes practical when data, optimization, and FP8 systems are designed together.
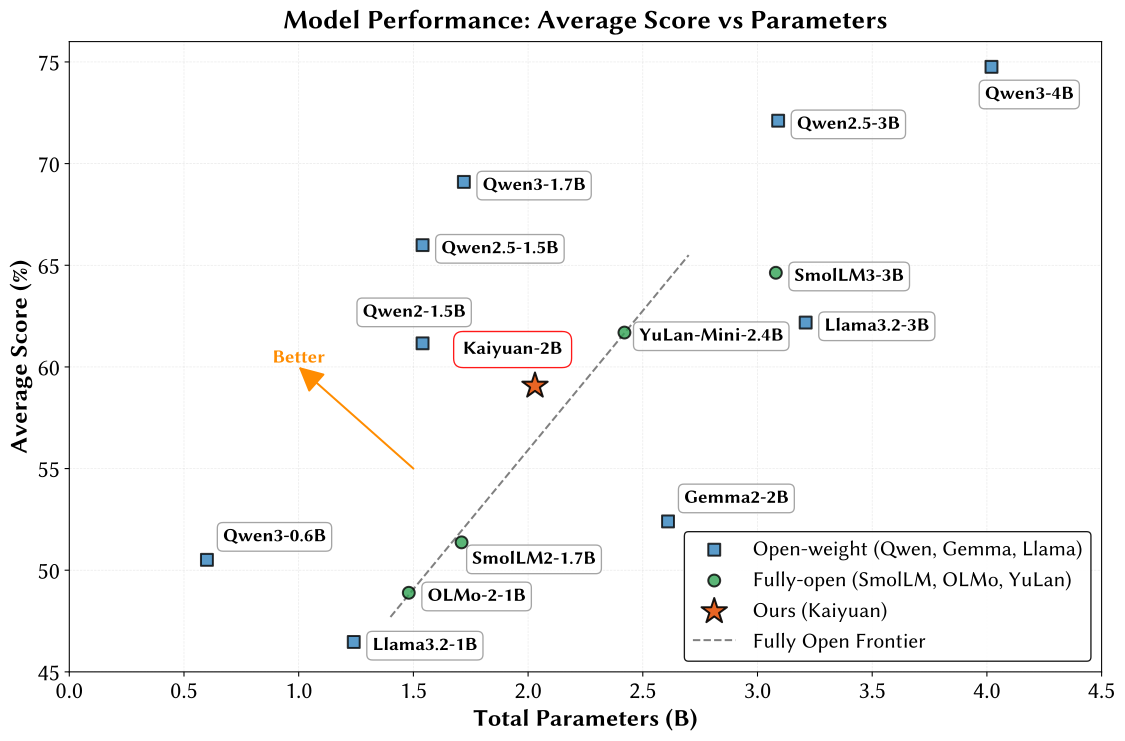
Comparing web corpora across quality quantiles helps choose better data mixtures for open LLM pretraining.
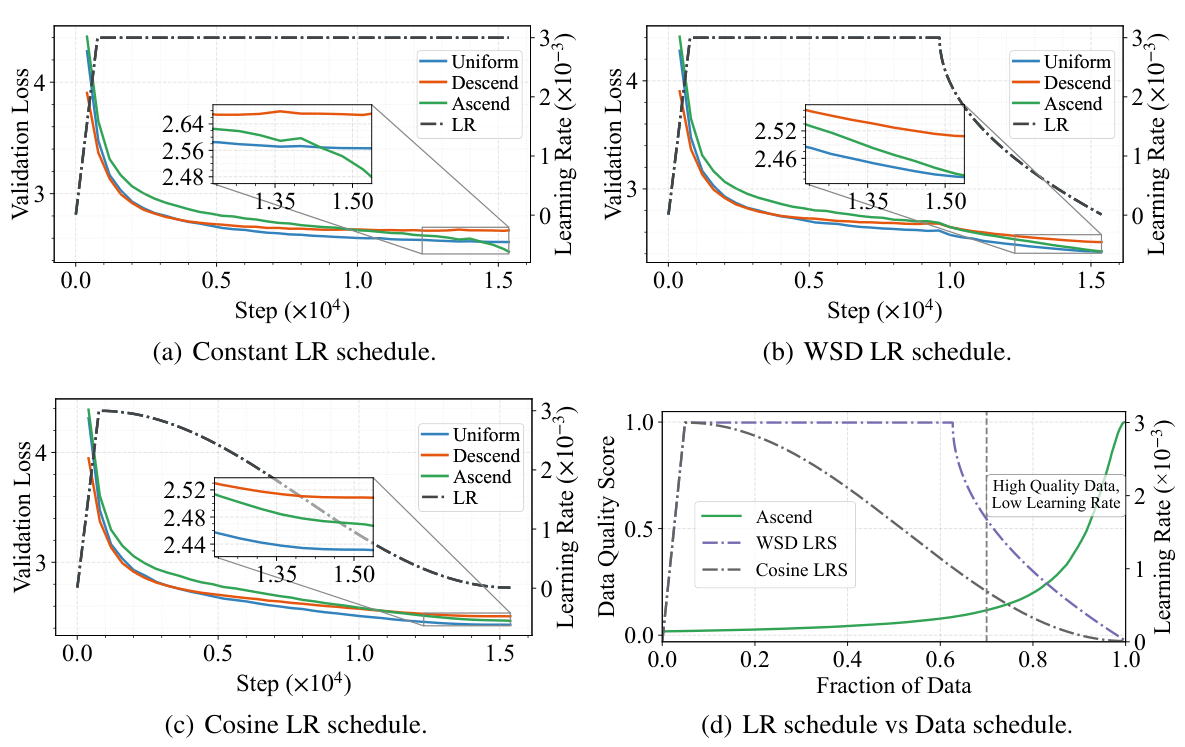
Learning-rate decay weakens late-arriving high-quality data, while moderate decay and curriculum model averaging recover its training benefits.
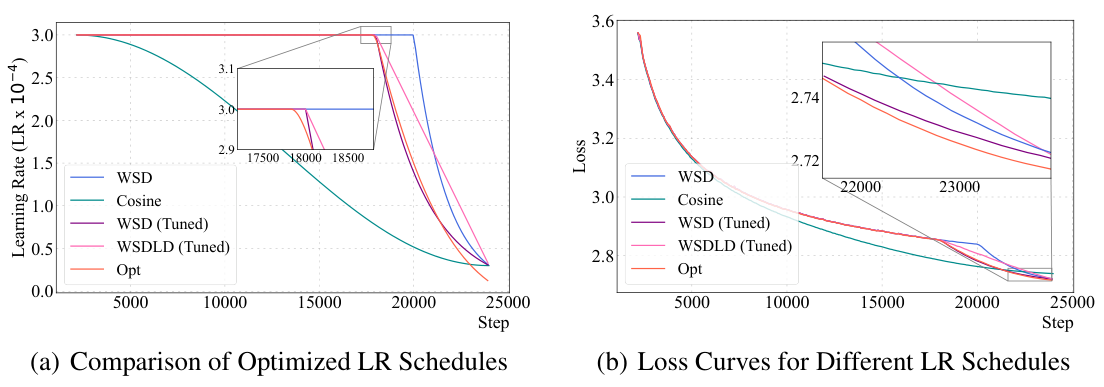
A multi-power law predicts loss under unseen learning-rate schedules, turning schedule selection from trial and error into a guided search.