RoBSA: RoPE-based Blockwise Sparse Multi-head Latent Attention
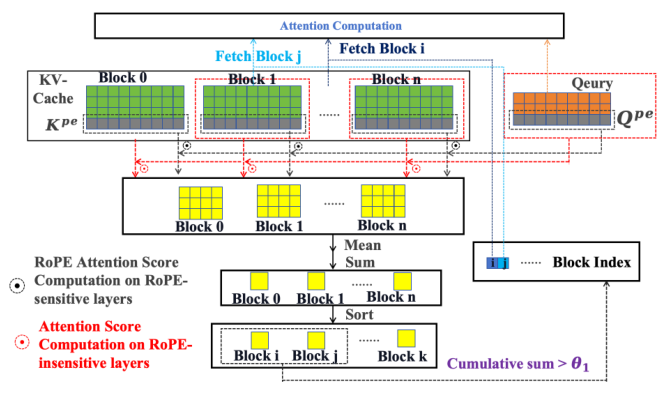
Training-free blockwise sparse attention for MLA reduces long-context decoding latency with minimal accuracy loss.
- ACL 2026, Volume 1: Long Papers, pp. 1028–1044
- My contributions: experiment analysis; assistance with paper writing
- ACL Anthology
RoBSA is a lightweight, training-free, and layer-aware blockwise sparse attention method designed for Multi-head Latent Attention during long-context decoding.
Xinyu Shi, Kairong Luo, Zhen Zheng, and Wenguang Chen. (2026). "RoBSA: RoPE-based Blockwise Sparse Multi-head Latent Attention." ACL 2026.